
The Week Ahead
Nvidia’s Jensen Huang called GPT-6 Astra AGI as Anthropic contracted 14.8 GW of compute, while the Fed’s September decision hinges on…
NASDAQ
NVDA
251 stories
$4.6T Market cap · 2026-11-06
Get NVDA news in Claude, ChatGPT or your own code. See plans
Nvidia’s Jensen Huang called GPT-6 Astra AGI as Anthropic contracted 14.8 GW of compute, while the Fed’s September decision hinges on…
Kirin 9050 Pro is the first Tau Scaling chip. The bigger story is Ascend. Huawei just put LogicFolding in the Mate XT 2. First commercial SoC on the Tau (τ) law He Tingbo laid out in May / updated in July. Not a surprise if you read that paper. Still a real jump: DUV + SAQP + logic stacking took density from 155 → 238 MTr/mm² on the same SMIC N+3 node. +55% in one gen. Power went down, not up. That’s N3-class equivalent density. Headline number matches Intel 18A HD (238) and sits next to Samsung SF2 (~231). TSMC N2 HD is still ahead (~313). Caveat: 238 is Huawei’s LogicFolding equivalent, not a planar N3 shrink. Same device node as 9030 Pro. Some analysts put the industry-formula read closer to ~175. Mobile scoreboard vs last-gen trifold / 9030 Pro: • Device +42% • CPU ST +24% / MT +52% • P-core 3.1 GHz (was 2.75) • CPU / GPU / NPU iso-perf power −41% / −58% / −66% • GPU render +142% • On-device 30B-total-param MoE Multi-core still trails $QCOM’s latest. The gap is no longer multi-generation. Next Tau Kirin can catch, maybe pass, a leading-edge mobile SoC. The packaging tell is sharper than the phone benches. 1.4–1.5μm hybrid-bond pitch. ~50M vertical interconnects. Western HVM hybrid bonding is still ~6μm (TSMC SoIC) to ~9μm (Intel Foveros Direct). If 1.4μm holds, that is SOTA vs Western leading-edge bonding — not the Geekbench print. Phone catch-up is the demo. AI silicon is the payoff. Apply the same fold to Ascend and the process-density gap vs $NVDA peers compresses from the lithography side over the next few quarters. Remaining bottlenecks: domestic DUV tool volume, HBM, packaging, software. I wouldn’t assume they outproduce ASML on DUV. I also wouldn’t fade the direction. Mature DUV + stacking + almost-unlimited power is enough to put China in the token-factory fight vs the US. Tables below. 🧵
GPT-6 Astra: scaling still works. Algo is the larger remaining gap. Astra shows both scaling laws and algorithms are still progressing. It is reportedly distilled from a 10T+ teacher named Bel. Maybe with $NVDA Vera Rubin and the next compute generation coming online, 10T+ becomes the new standard and performance keeps compounding. That means continued — even accelerating — demand for AI infra. The more interesting signal is algo. IMO we are still just touching the surface of how algorithms can improve. There is still a large gap between SOTA perf/watt and the human brain. GPT-6’s recurrent depth is the part that stuck with me. CoT / test-time reasoning lets the model write intermediate steps out as tokens, then produce a better final answer than a direct reply. Recurrent depth is different. It lets the model think longer and harder in hidden space before any word is emitted. Not just write the thinking out. Think harder on each next bit of the word. I am perplexed this arrived so late in GPT-6. Stable Diffusion introduced and spread this kind of latent iterative method in image generation ~5 years ago. The main reason it came so late: hidden thinking is harder to safety-check and monitor than explicit CoT. That constraint is real. It is also more human-like. People do not narrate every step. Plenty of global-max algorithms are still unimplemented for similar reasons. Models only get stronger from here.
OpenAI's potential failure could expose the US economy's growing dependence on AI capital spending, according to Steve Eisman.
Nvidia’s $12.93 billion Hugging Face acquisition pays 86 times annualized revenue for control of an AI developer ecosystem spanning 18…
 High Alpha Professor
Open weight model to Nvidia ls kerosene lamp to Standard Oil. Free access to models = more demand for underlying infra. What's better is $NVDA can make this Lamp tailored and optimized for Nvidia stack such that users have to pick: Free model + $NVDA stack or Expensive model + Non-NVDA stack. The question is more about if $NVDA can deliver frontier open weight models or not. I am still a bit skeptical about it because it takes an elite dedicated team to do that and $META learned that hard lesson. And it also requires visionary mgt directly leading the elite team which $GOOG and $MSFT failed, while $SPCX realized it and back up again.
During the Iran dip initially there was a lot of behind the scenes AI progress. And so when there was finally relief — in the form of the initial detente -> MOU — things totally ripped. I feel like with these insane $NVDA and $AVGO guides we are almost in this spot again. Hedge funds have delevered, momo has been historically crushed, Warsh has said a lot of hawkish things, and the next FOMC the market expects a hike. Obviously the big overhang is yields. But it feels to me like for all the discussion of guidance/rates/the yield curve… really the bond market just wants the war to end or at least be paused. I am not so sure that the US has no power to at least have things significantly deescalate when it wants (maybe into midterms). It’s like, we can “lose” a war, but Iran can still recognize that with time its leverage will decrease, its economy will be destroyed further… like it seems a bit naive just to think that because the war is going badly, Iran has no desire to see it wind down. This latest tit for tat for example hasn’t been that crazy. So IF you think that we get some sort of detente, which is really what I think yields need — are we not kind of a coiled spring here and running back a similar setup to when things started ripping?
Nvidia’s Q2 2027 triple-digit growth and above-consensus FY28 outlook reinforce AI infrastructure spending, while Symbotic’s new automation…
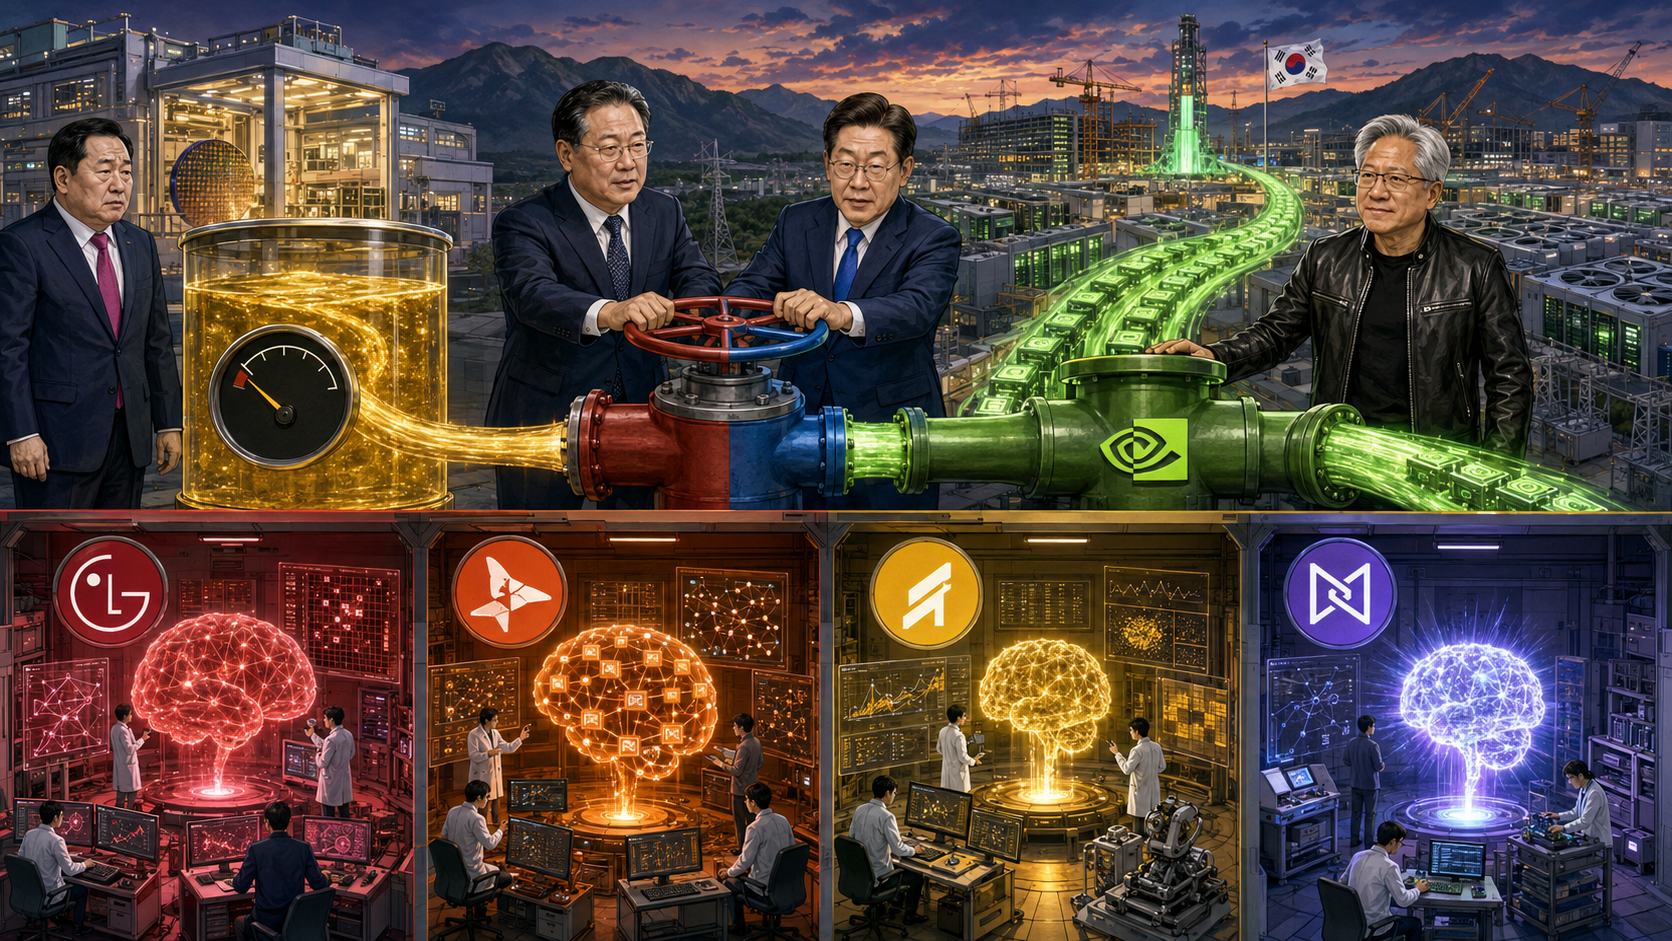
South Korea’s sovereign AI push channels GPU spending to Nvidia while domestic-model ambitions risk conflicting with Samsung and SK Hynix…
*ANTHROPIC SIGNS $35B CLOUD DEAL WITH LAMBDA IN TEXAS: WSJ $NVDA holding the lease, developed by $HUT
$NVDA now trades under 10x GS’s updated 2028 EPS estimates, per GS’s Peter Callahan:
FT: Big tech giants booked a $160B+ windfall last qtr from investments in other AI companies. $GOOG, $AMZN, $NVDA, & $MSFT all had lg boosts to their pre-tax profits from ‘other income’ in theory P&L, due largely to valuation gains on equity stakes in other leading AI companies

AI beneficiaries Nvidia, TSMC, Alphabet, Amazon and SK hynix delivered sharply higher earnings alongside share gains, keeping forward…
Why does he think hedge fund analysts “missed” $NVDA? Every fund I know has been long for some part of the last 5+ years. Did he think it became the most valuable stock in the world from just him (the only hedge fund to own it) and mutual funds? Bull market genius.
Man in just 48 hours we went from the $DRAM bulls tap-dancing and high fiving on the "incredible" $160B Q/Q (it is crazy) increase in supply and purchase agreements from $NVDA to: "The memory names have held up well on a relative basis the past two days".... Two golden rules apply here: 1) The market will pick the path of the most pain 2) Karma has everyone's address so please stop with your victory laps, lectures, and bear trouncing. This game is hard and unforgiving.
$SOXX $NVDA down since the big beat... sure looks like a news failure event. I think it'll be electricity bottlenecks that kill the AI hardware bubble. The hyperscalers controlling that bottleneck should be the biggest winner.
@Kcon2026 didn’t miss that. i was long calls going into $NVDA earnings. my comment was about other investors making outsized bets long or short based mostly on vibes.
 NVDA 2026-08-28
Nvidia’s fiscal 2028 outlook, Vera Rubin’s $40 billion per gigawatt content, OpenAI’s Jalapeño chip, and $500 billion in commitments…
 Ivana Delevska 2 clicks
Nvidia’s $6 billion Poolside licensing deal aims to build a leading U.S.
Nvidia’s earnings report follows Danny’s pre-results long NVDA call and prompts a review of his “Bullmonia.
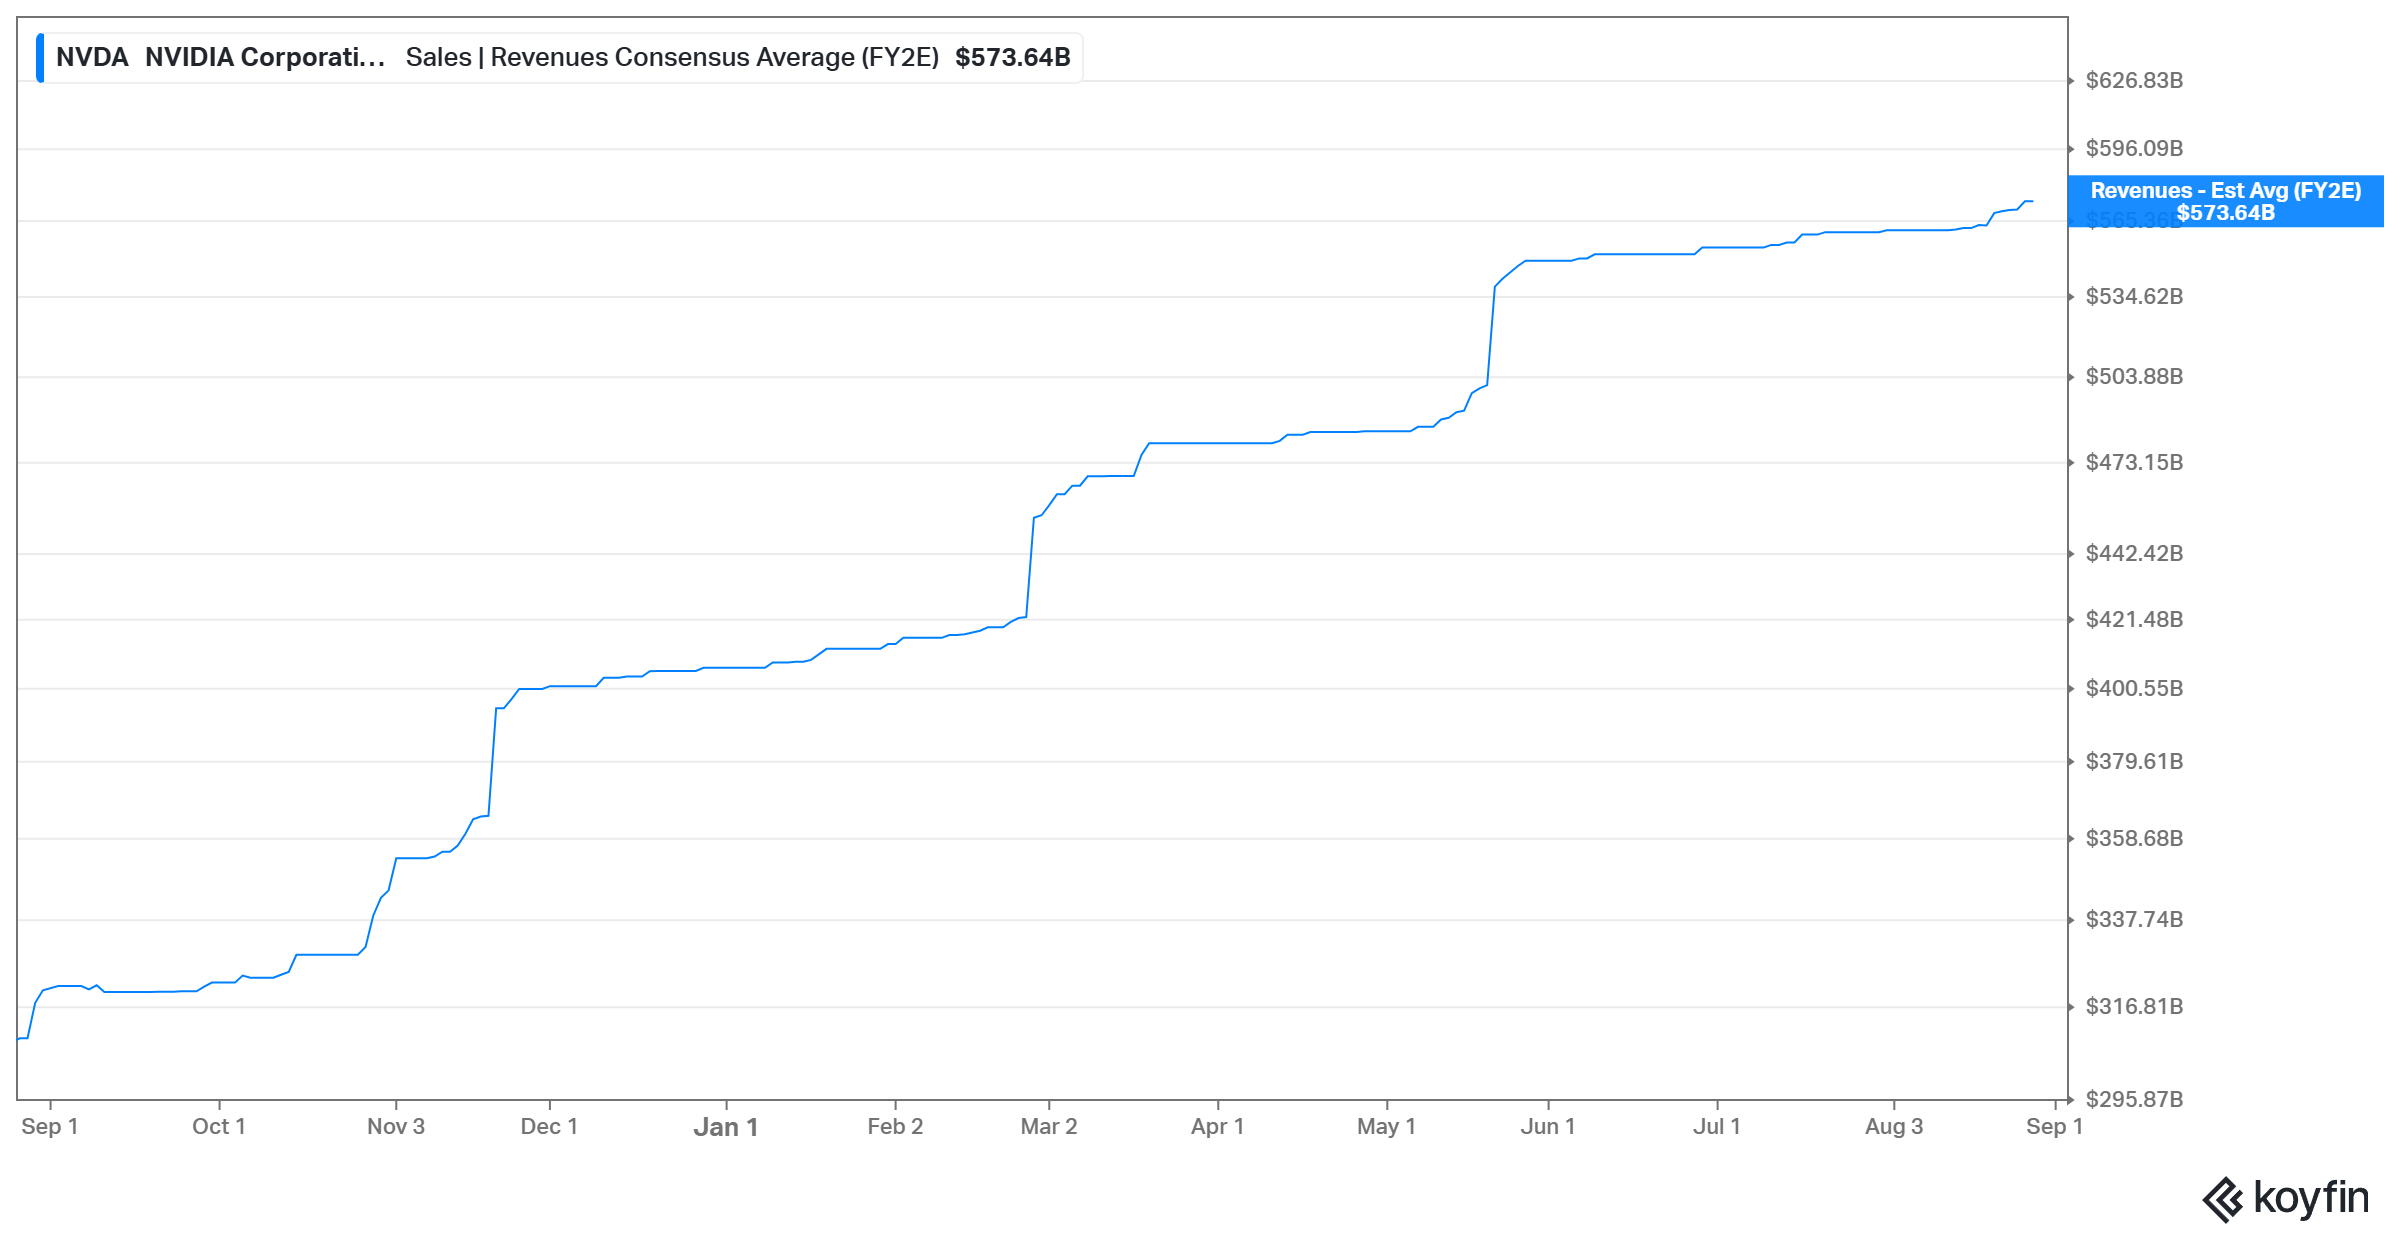
Nvidia guided FY2028 revenue toward $700 billion, roughly 70% growth, while supply constraints and neocloud demand face concerns over…
70% FY28 revenue growth is incredible, but if you were an $NVDA bear before that call, it’s very unlikely that view has changed (sure maybe funding shorts get covered) The bear argument is more intact than ever. Nvidia’s demand, while very robust, still comes in part from largely unprofitable companies/labs which are of course dependent on Nvidia for financing Jensen addressed these concerns directly, saying "frontier labs sales are skyrocketing, their margins are fantastic…they're generating profitable tokens…they're only limited by the amount of compute” The bear argument isn't going to be solved by fantastic numbers in any given quarter, it will take lots of time to be proven right or wrong
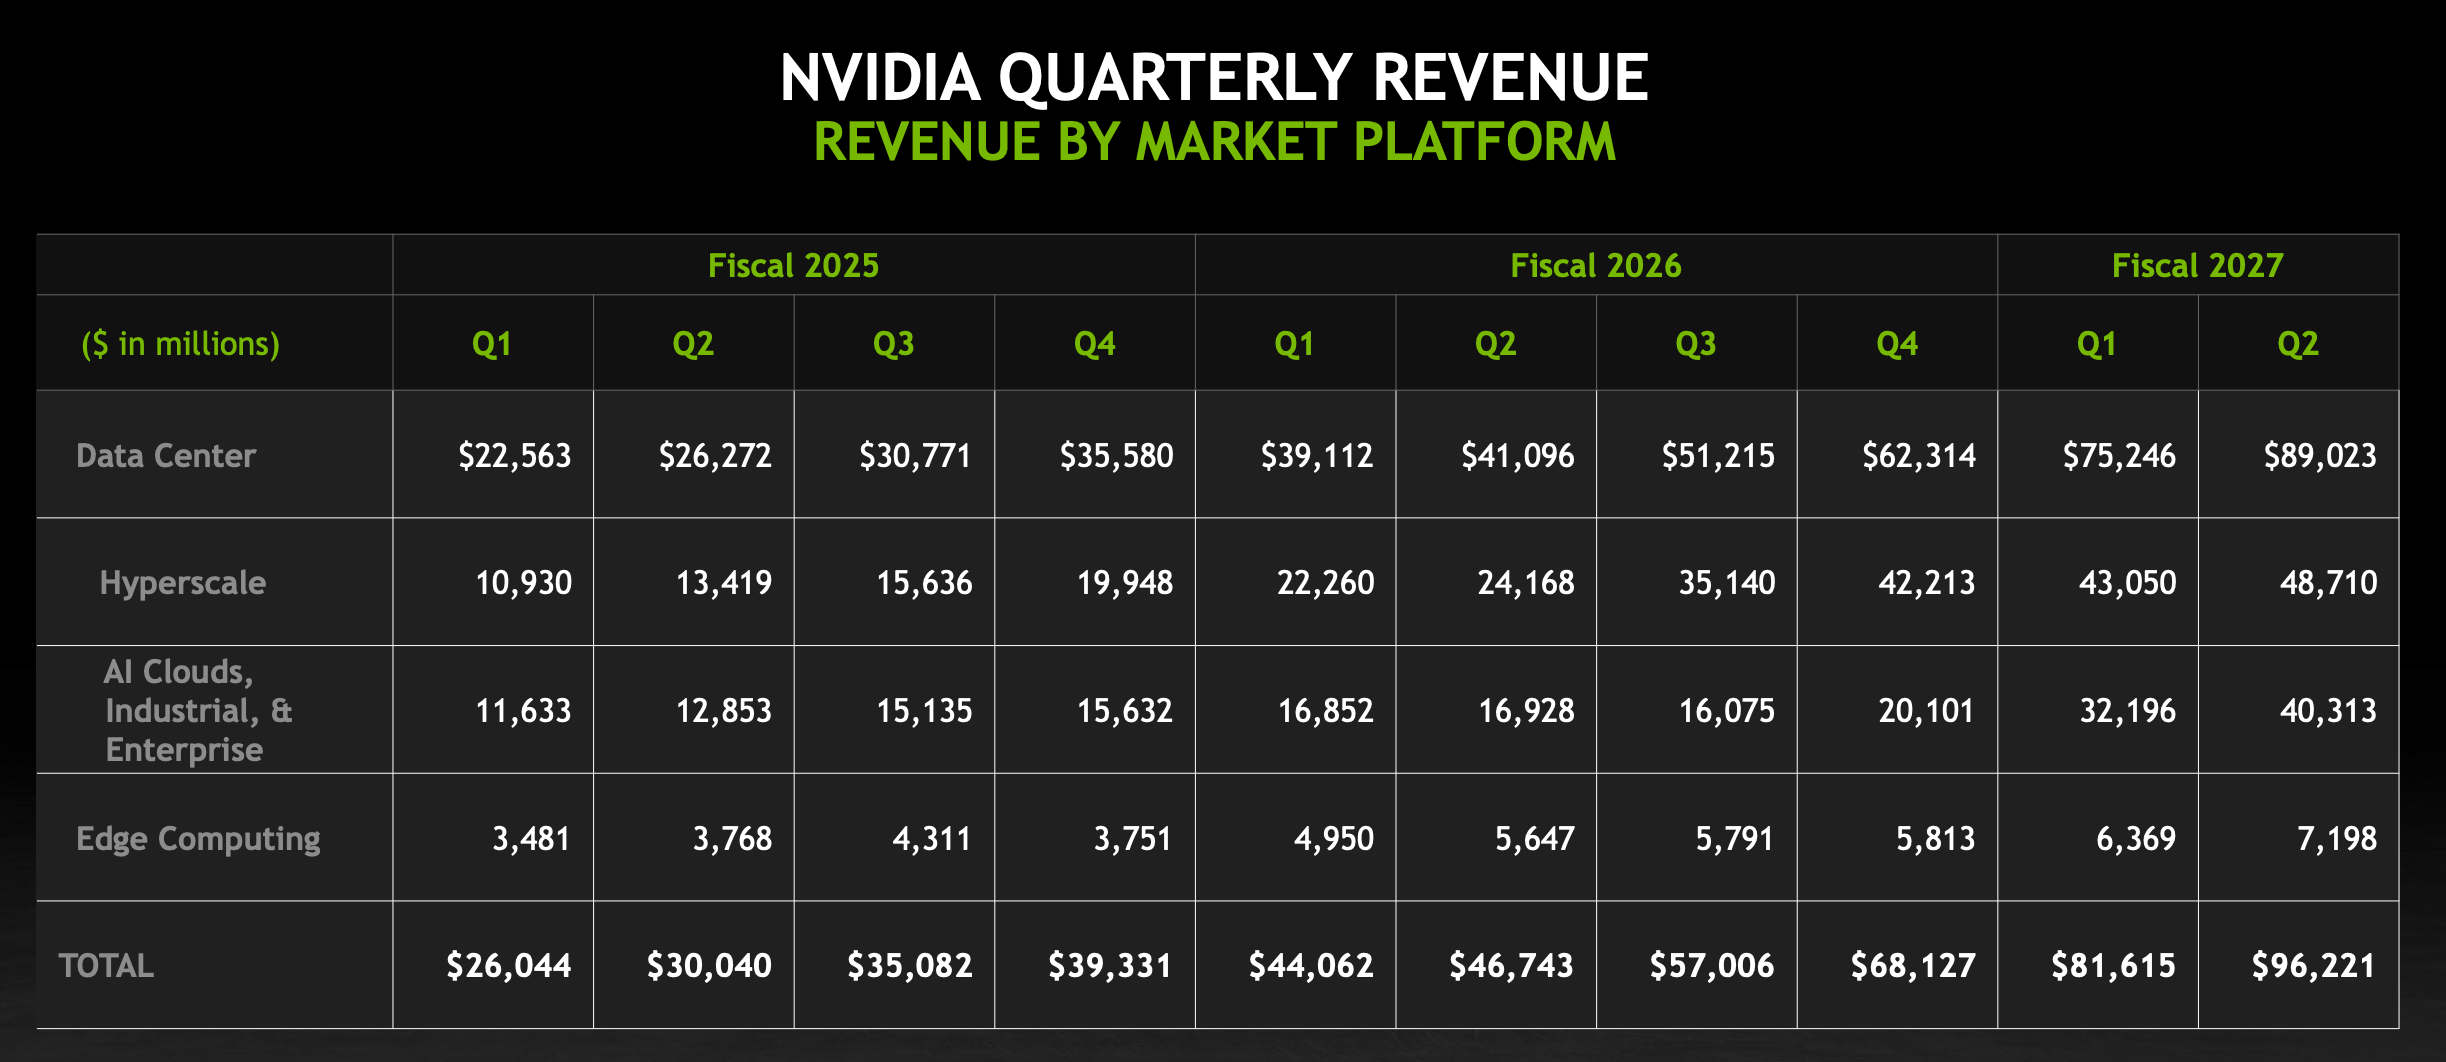
Nvidia reported $96.2 billion in quarterly revenue and forecast roughly 70% fiscal 2028 growth, constrained by component supply despite…

Nvidia’s Q2 earnings drove overnight gains as markets awaited Thursday’s close, while the review tracked Treasuries, gold, oil, crypto and…
Letters that discuss NVDA.
Companies the stories above are also about, besides NVDA.


